<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://chengan-che.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://chengan-che.github.io/" rel="alternate" type="text/html" /><updated>2026-07-23T22:02:20+00:00</updated><id>https://chengan-che.github.io/feed.xml</id><title type="html">Chengan Che</title><subtitle>Personal academic website of Chengan Che</subtitle><author><name>Chengan Che</name><email>chengan.che@kcl.ac.uk</email></author><entry><title type="html">PL-Stitch</title><link href="https://chengan-che.github.io/research/pl-stitch/" rel="alternate" type="text/html" title="PL-Stitch" /><published>2026-06-02T00:00:00+00:00</published><updated>2026-06-02T00:00:00+00:00</updated><id>https://chengan-che.github.io/research/pl-stitch</id><content type="html" xml:base="https://chengan-che.github.io/research/pl-stitch/"><![CDATA[<p><img src="/images/publications/poster_cvpr26_pl.png" alt="PL-Stitch poster" /></p>

<h2 id="a-stitch-in-time-learning-procedural-workflow-via-self-supervised-plackett-luce-ranking">A Stitch in Time: Learning Procedural Workflow via Self-Supervised Plackett-Luce Ranking</h2>

<p><strong>Chengan Che</strong>, Chao Wang, Xinyue Chen, Sophia Tsoka, Luis C. Garcia-Peraza-Herrera</p>

<p><strong>CVPR 2026</strong></p>

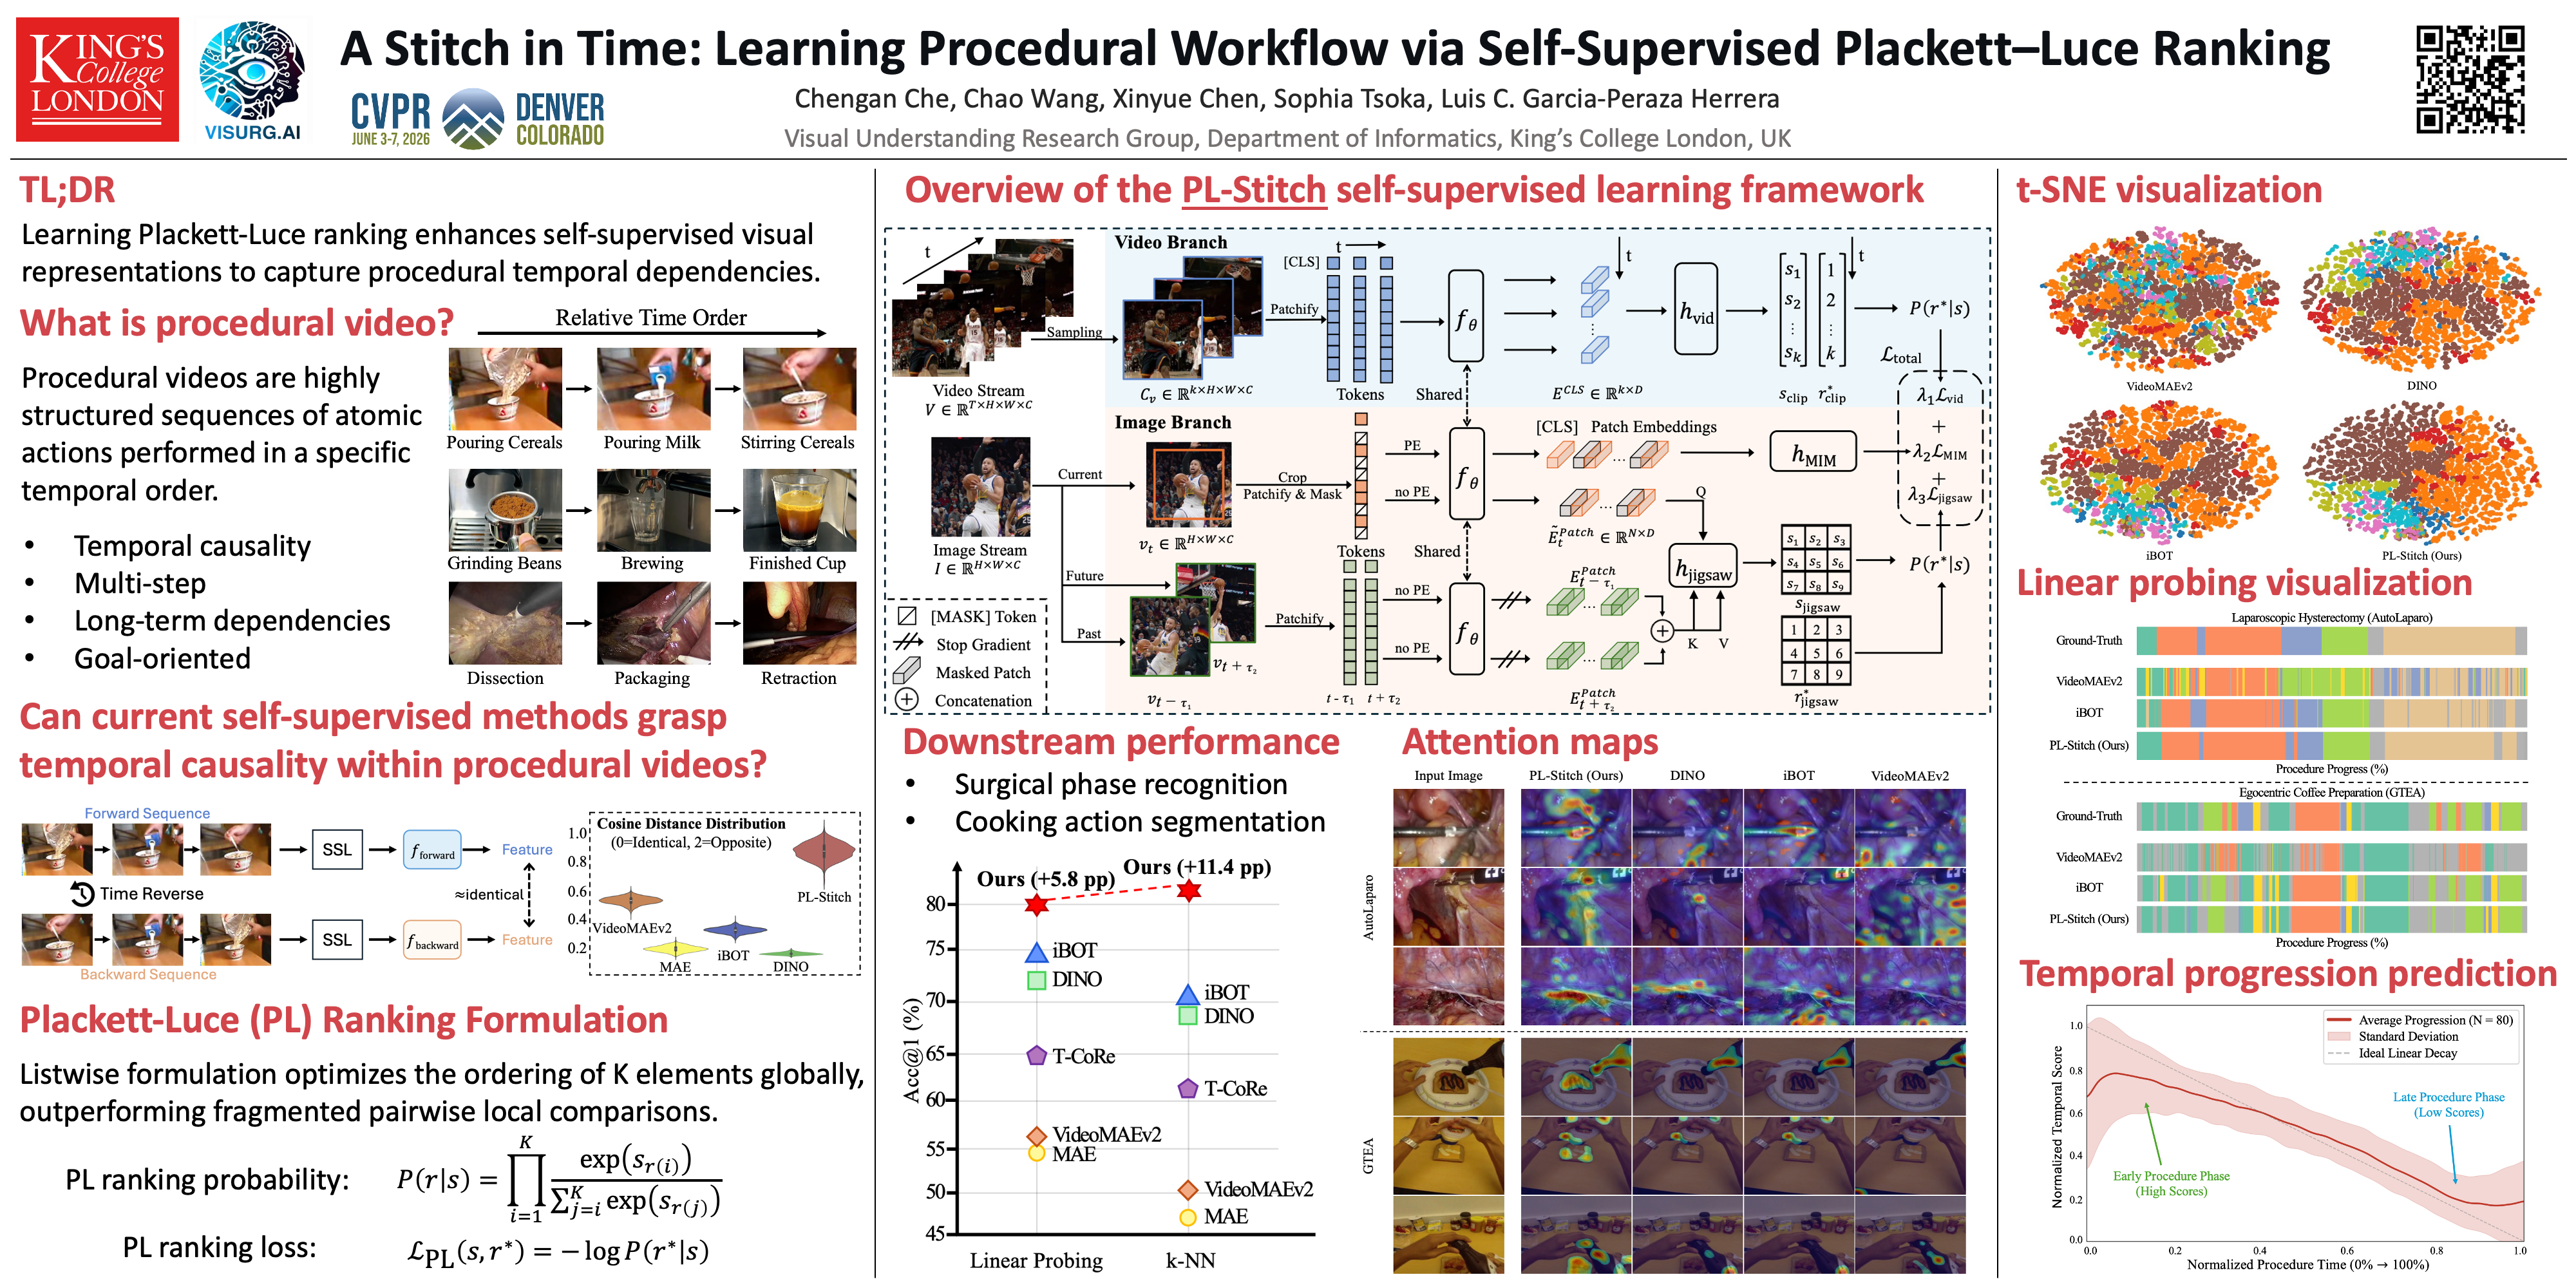
<p>PL-Stitch learns procedure-aware video representations by formulating temporal ordering as a probabilistic listwise ranking problem. It combines global temporal ranking with a spatio-temporal jigsaw objective to capture both procedural progression and fine-grained temporal correspondence.</p>

<p><a href="https://openaccess.thecvf.com/content/CVPR2026/papers/Che_A_Stitch_in_Time_Learning_Procedural_Workflow_via_Self-Supervised_Plackett-Luce_CVPR_2026_paper.pdf">Paper</a> · <a href="https://github.com/visurg-ai/PL-Stitch">Code</a></p>]]></content><author><name>Chengan Che</name><email>chengan.che@kcl.ac.uk</email></author><summary type="html"><![CDATA[Self-supervised learning of procedure-aware video representations through probabilistic listwise temporal ranking.]]></summary></entry><entry><title type="html">LEMON</title><link href="https://chengan-che.github.io/research/lemon/" rel="alternate" type="text/html" title="LEMON" /><published>2026-06-01T00:00:00+00:00</published><updated>2026-06-01T00:00:00+00:00</updated><id>https://chengan-che.github.io/research/lemon</id><content type="html" xml:base="https://chengan-che.github.io/research/lemon/"><![CDATA[<p><img src="/images/publications/poster_cvpr26_lemon.png" alt="LEMON poster" /></p>

<h2 id="lemon-a-large-endoscopic-monocular-dataset-and-foundation-model-for-perception-in-surgical-settings">LEMON: A Large Endoscopic MONocular Dataset and Foundation Model for Perception in Surgical Settings</h2>

<p><strong>Chengan Che</strong>, Chao Wang, Tom Vercauteren, Sophia Tsoka, Luis C. Garcia-Peraza-Herrera</p>

<p><strong>CVPR 2026</strong></p>

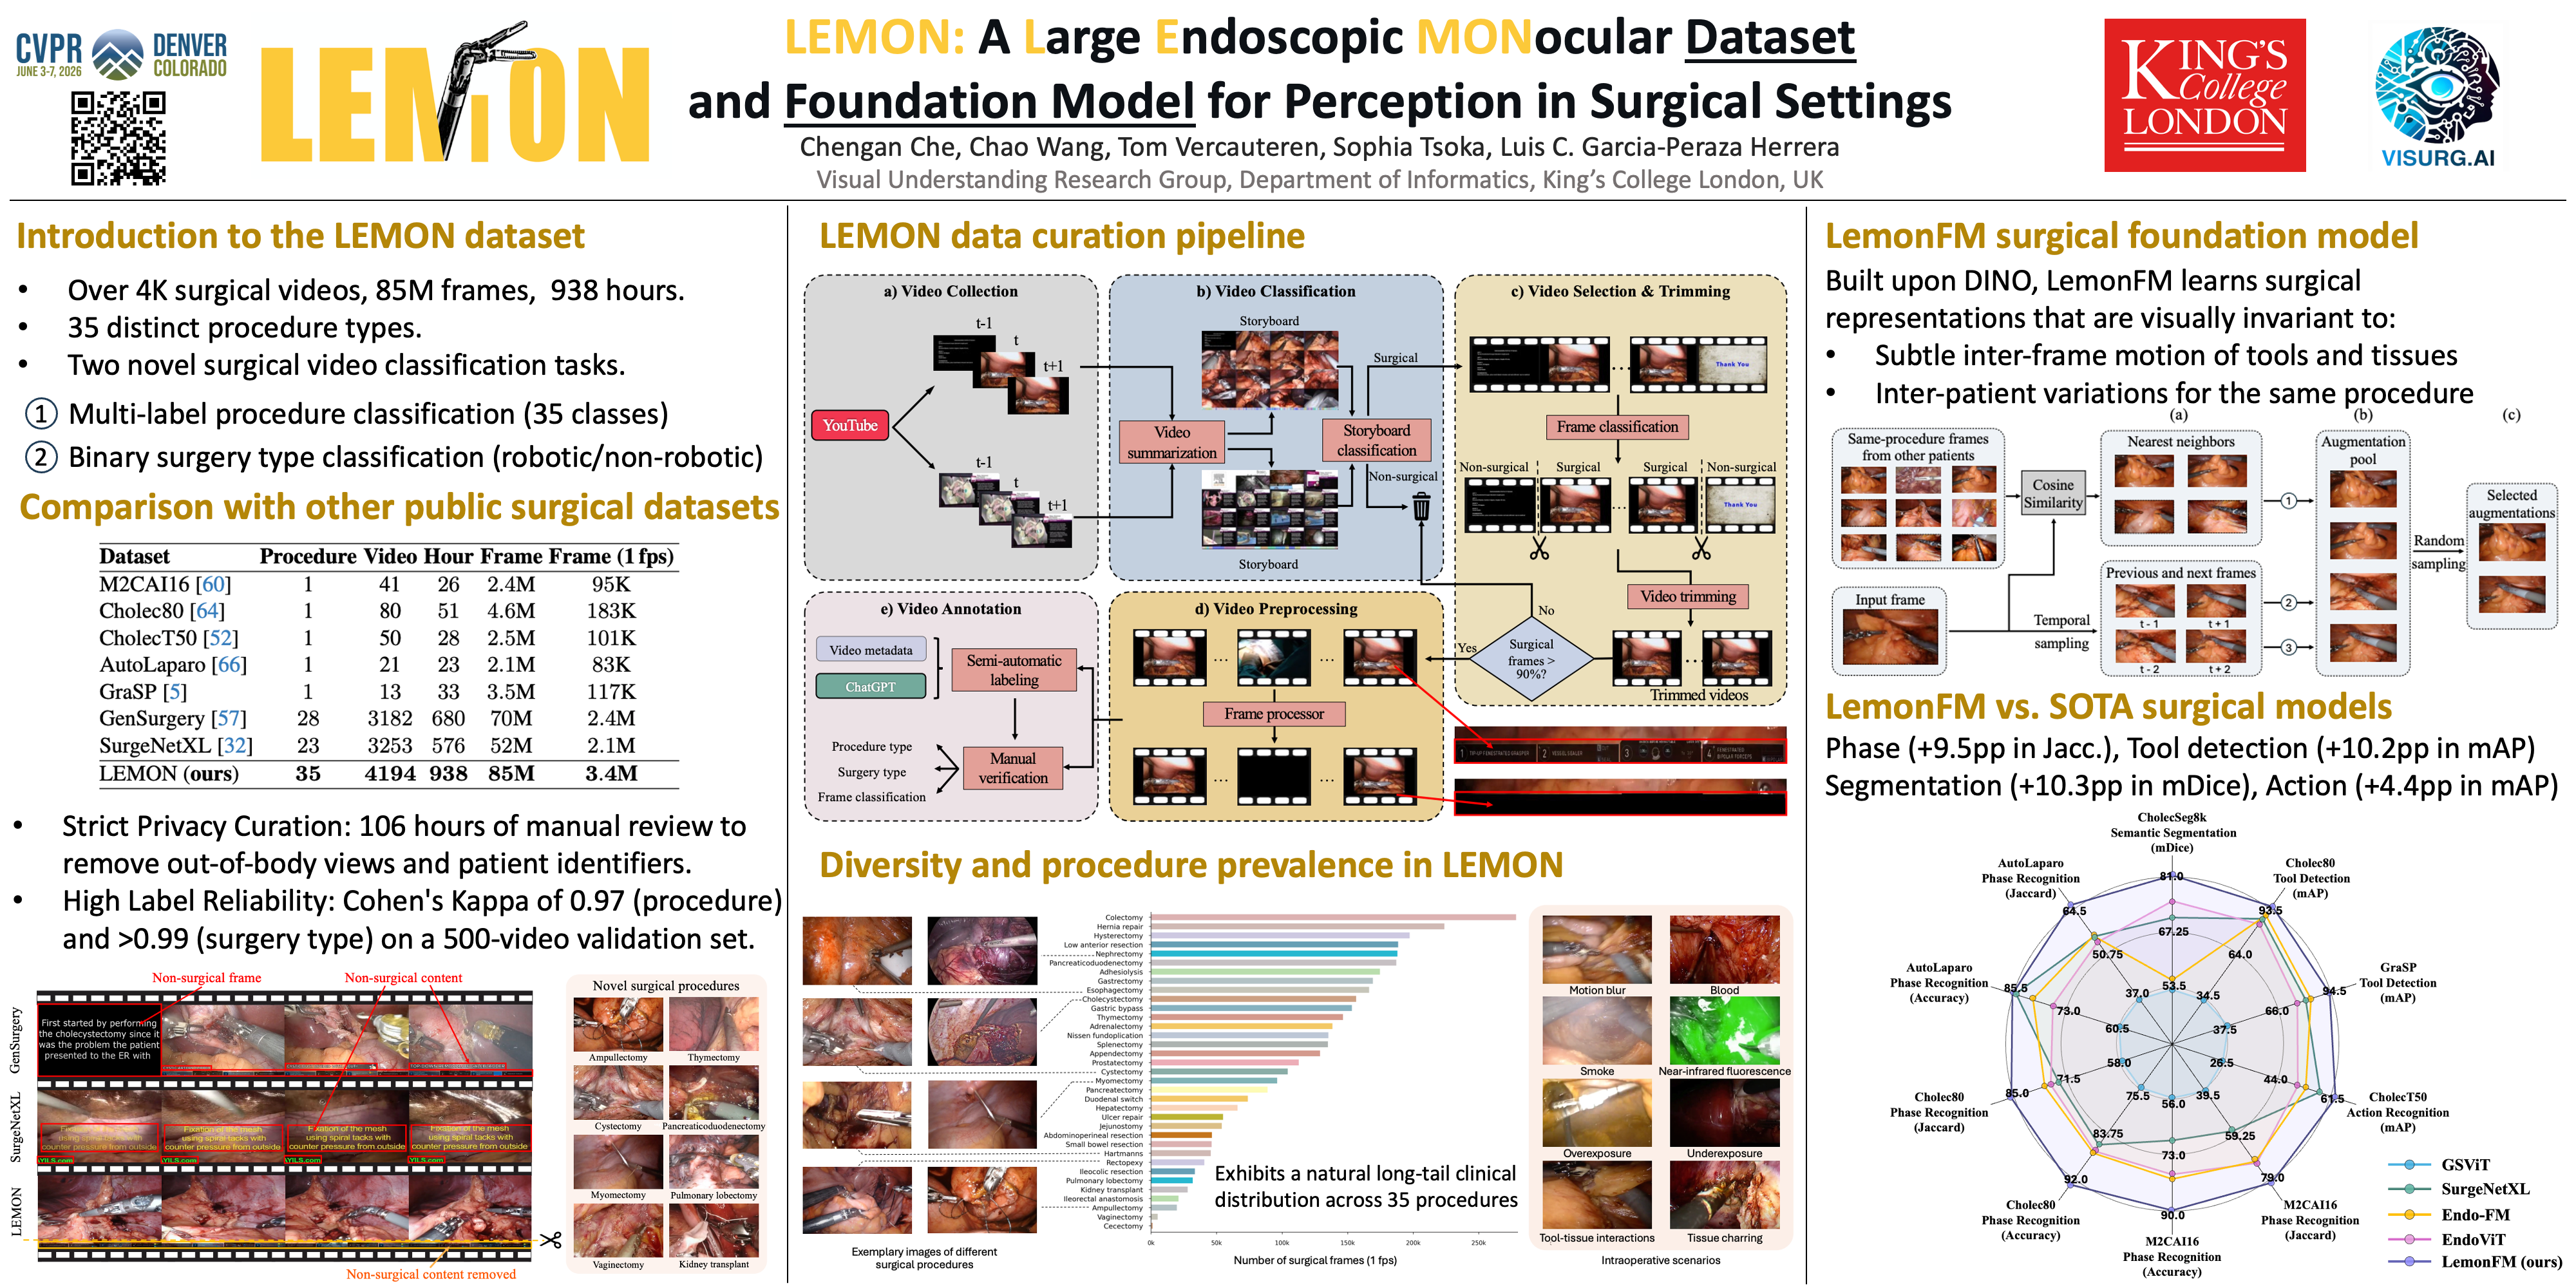
<p>LEMON is a large-scale open-access surgical video dataset comprising 4,194 long-form videos, approximately 938 hours of footage, and 85 million frames across 35 surgical procedures.</p>

<p>To curate this dataset, we developed a highly automated pipeline for collecting, filtering, and processing unconstrained surgical videos. We further pretrained LemonFM on LEMON using an augmented self-distillation framework, producing transferable visual representations for surgical video understanding.</p>

<p>LemonFM achieves strong performance across multiple downstream tasks, including surgical phase recognition, tool and action recognition, and semantic segmentation.</p>

<p><a href="https://openaccess.thecvf.com/content/CVPR2026/papers/Che_LEMON_A_Large_Endoscopic_MONocular_Dataset_and_Foundation_Model_for_CVPR_2026_paper.pdf">Paper</a> · <a href="https://github.com/visurg-ai/LEMON">Code</a></p>]]></content><author><name>Chengan Che</name><email>chengan.che@kcl.ac.uk</email></author><summary type="html"><![CDATA[A large-scale open-access surgical video dataset and foundation model for transferable surgical visual representation learning.]]></summary></entry><entry><title type="html">SurgLIME</title><link href="https://chengan-che.github.io/research/surglime/" rel="alternate" type="text/html" title="SurgLIME" /><published>2026-05-30T00:00:00+00:00</published><updated>2026-05-30T00:00:00+00:00</updated><id>https://chengan-che.github.io/research/surglime</id><content type="html" xml:base="https://chengan-che.github.io/research/surglime/"><![CDATA[<p><img src="/images/publications/poster_cvprw26_surglime.png" alt="SurgLIME poster" /></p>

<h2 id="can-llm-generated-text-empower-surgical-vision-language-pre-training">Can LLM-Generated Text Empower Surgical Vision-Language Pre-training?</h2>

<p><strong>Chengan Che</strong><em>, <strong>Chao Wang</strong></em>, Jiayuan Huang, Xinyue Chen, Luis C. Garcia-Peraza-Herrera</p>

<p><strong>CVPR Workshops 2026, Oral Presentation</strong></p>

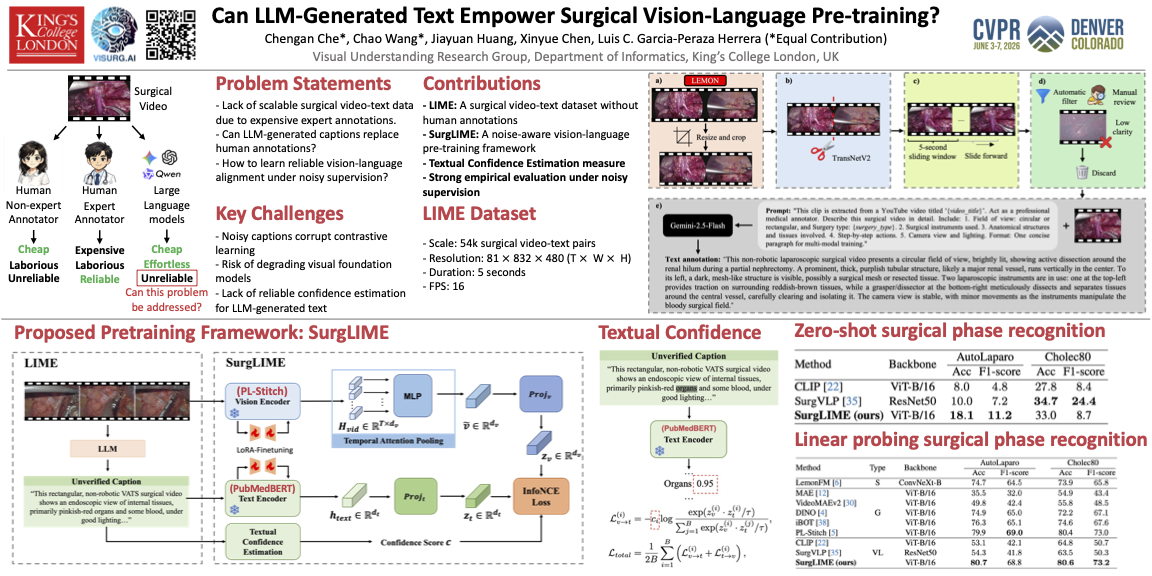
<p>SurgLIME enables scalable surgical vision-language pre-training using LLM-generated textual descriptions. It combines parameter-efficient vision-language alignment with a confidence-aware mechanism that reduces the contribution of less reliable generated text during training.</p>

<p>* Equal contribution.</p>

<p><a href="https://openaccess.thecvf.com/content/CVPR2026W/AI4RWC/papers/Che_Can_LLM-Generated_Text_Empower_Surgical_Vision-Language_Pre-training_CVPRW_2026_paper.pdf">Paper</a> · <a href="https://github.com/visurg-ai/SurgLIME">Code</a></p>]]></content><author><name>Chengan Che</name><email>chengan.che@kcl.ac.uk</email></author><summary type="html"><![CDATA[Scalable surgical vision-language pre-training with LLM-generated text and confidence-aware alignment.]]></summary></entry><entry><title type="html">Back to the Feature</title><link href="https://chengan-che.github.io/research/back-to-the-feature/" rel="alternate" type="text/html" title="Back to the Feature" /><published>2026-05-24T00:00:00+00:00</published><updated>2026-05-24T00:00:00+00:00</updated><id>https://chengan-che.github.io/research/bttf</id><content type="html" xml:base="https://chengan-che.github.io/research/back-to-the-feature/"><![CDATA[<p><img src="/images/publications/bttf.png" alt="Back to the Feature poster" /></p>

<h2 id="back-to-the-feature-explaining-video-classifiers-with-video-counterfactual-explanations">Back to the Feature: Explaining Video Classifiers with Video Counterfactual Explanations</h2>

<p>Chao Wang, <strong>Chengan Che</strong>, Xinyue Chen, Sophia Tsoka, Luis C. Garcia-Peraza-Herrera</p>

<p><strong>CVPR 2026</strong></p>

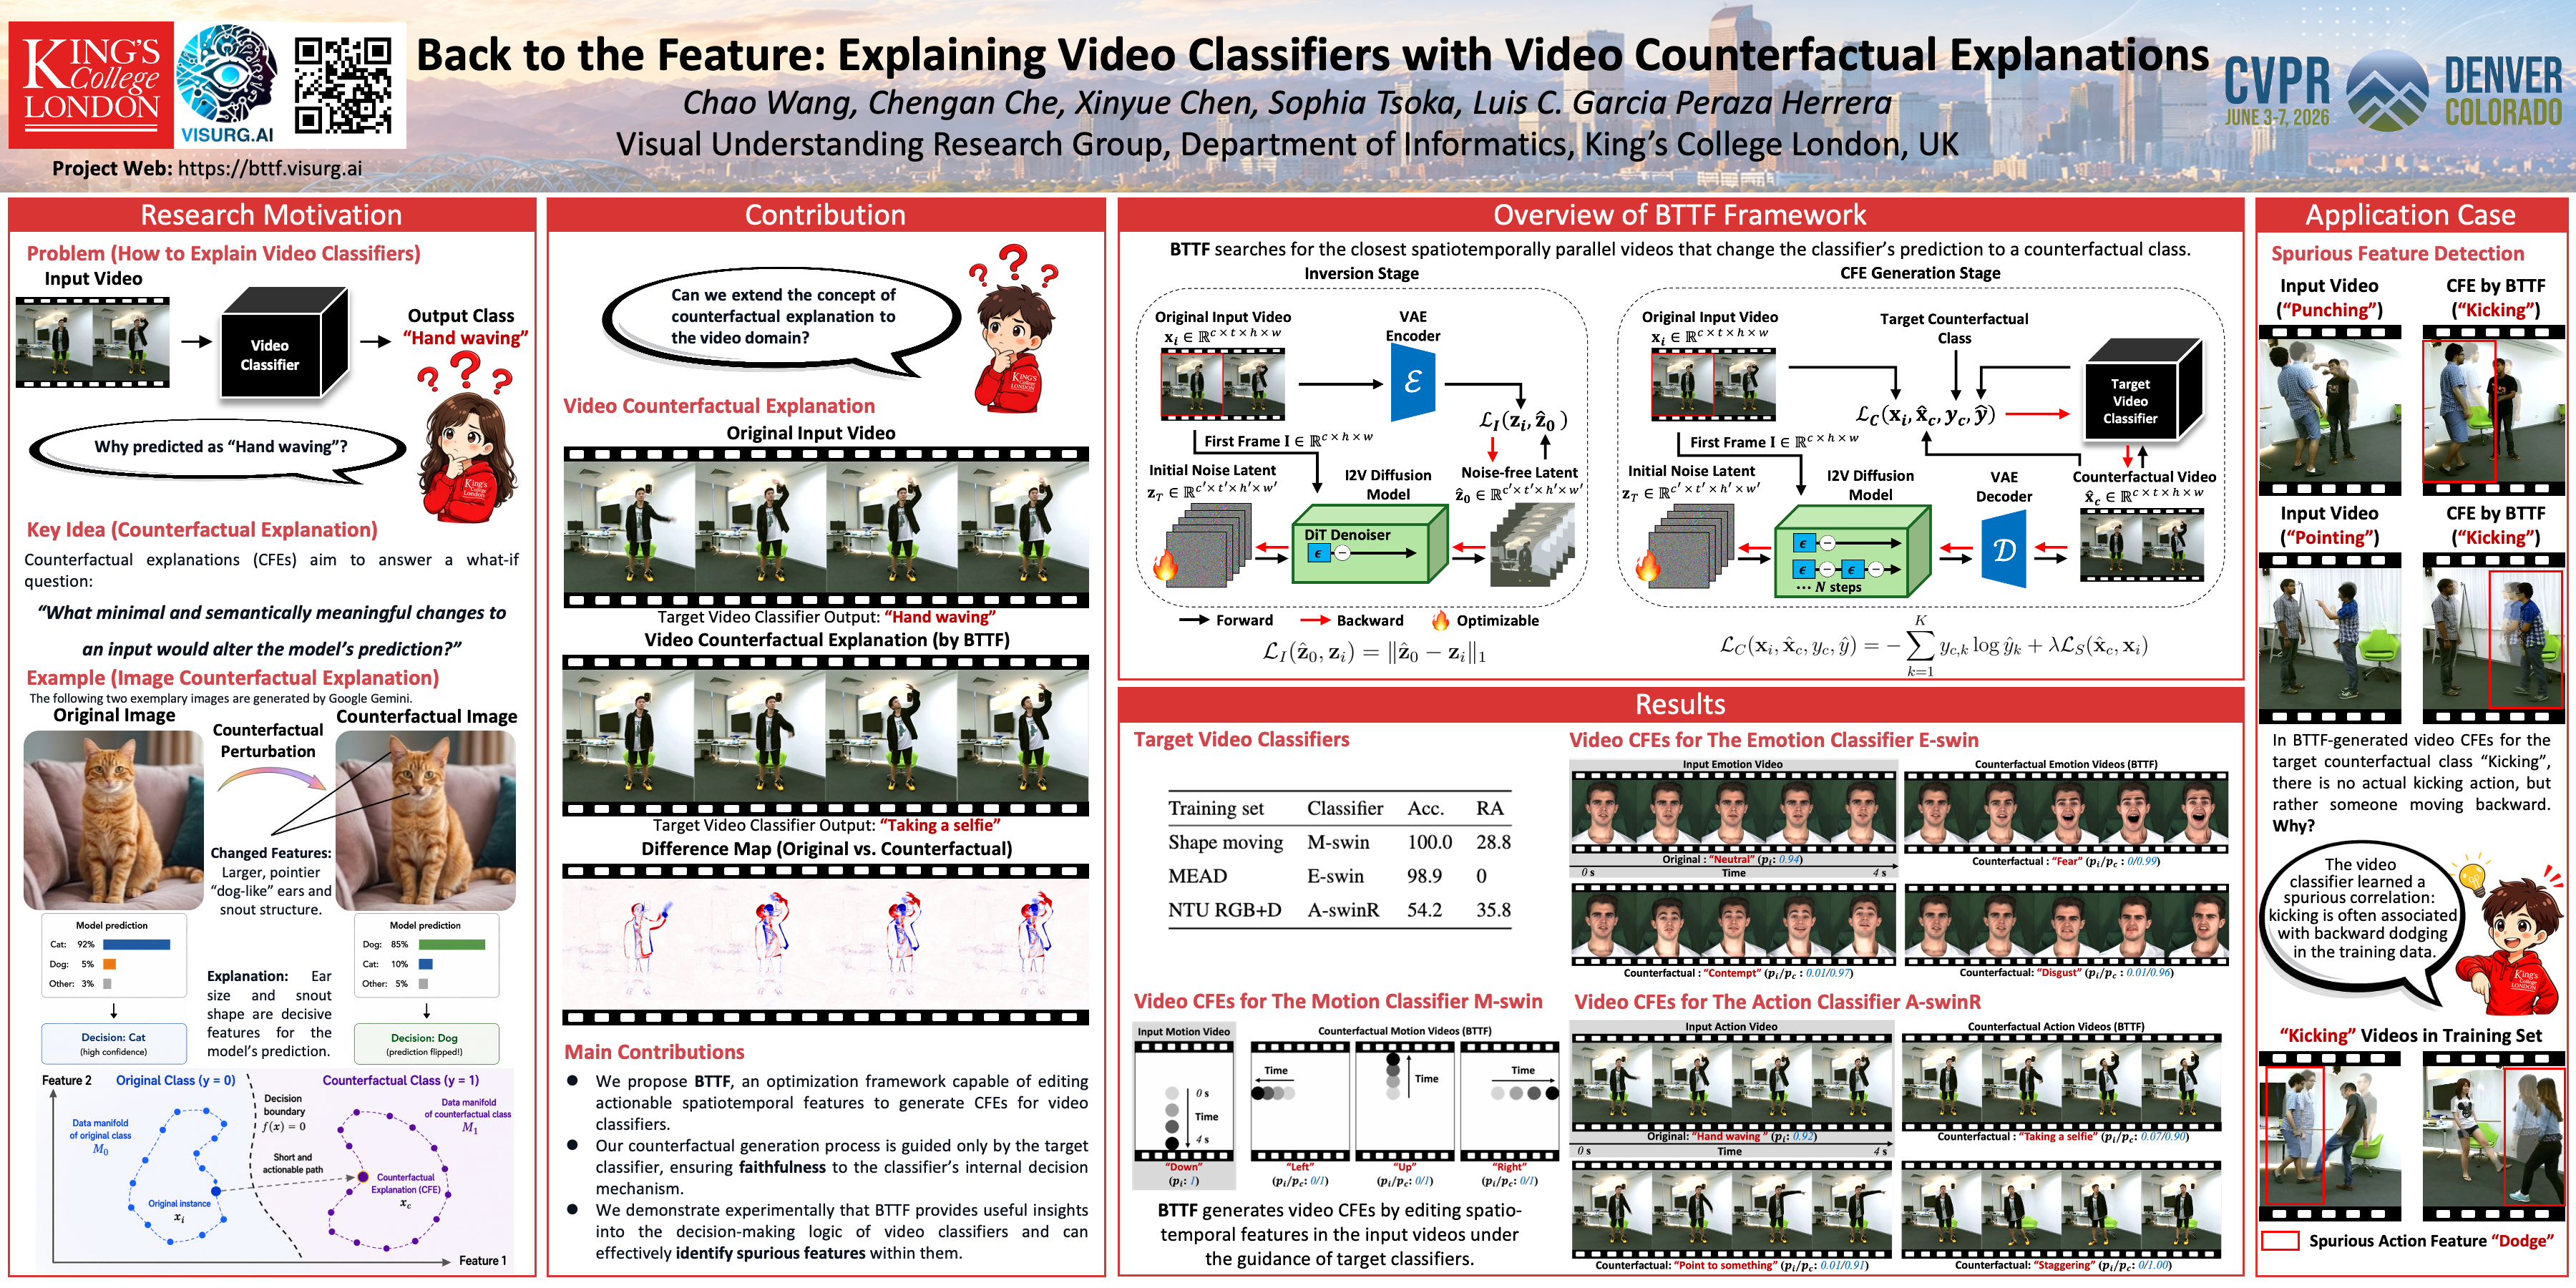
<p>Back to the Feature explains video classifiers by generating counterfactual examples in feature space. The method identifies changes that alter model predictions while preserving the temporal and semantic structure of the original video.</p>

<p><a href="https://openaccess.thecvf.com/content/CVPR2026/papers/Wang_Back_to_the_Feature_Explaining_Video_Classifiers_with_Video_Counterfactual_CVPR_2026_paper.pdf">Paper</a> · <a href="https://github.com/visurg-ai/BTTF">Code</a></p>]]></content><author><name>Chengan Che</name><email>chengan.che@kcl.ac.uk</email></author><summary type="html"><![CDATA[Explaining video classifiers through feature-level video counterfactual explanations.]]></summary></entry></feed>